LLM analytics
Token usage per user, model and session from your coding agents' telemetry, and sessions far above normal
Token use builds up across many developers and sessions, so no single person sees it. The LLM Usage tab of Activity › Enforcement Traffic shows tokens per user, model and session as trends. Dollar figures are on Cost and adoption.
What the tab shows
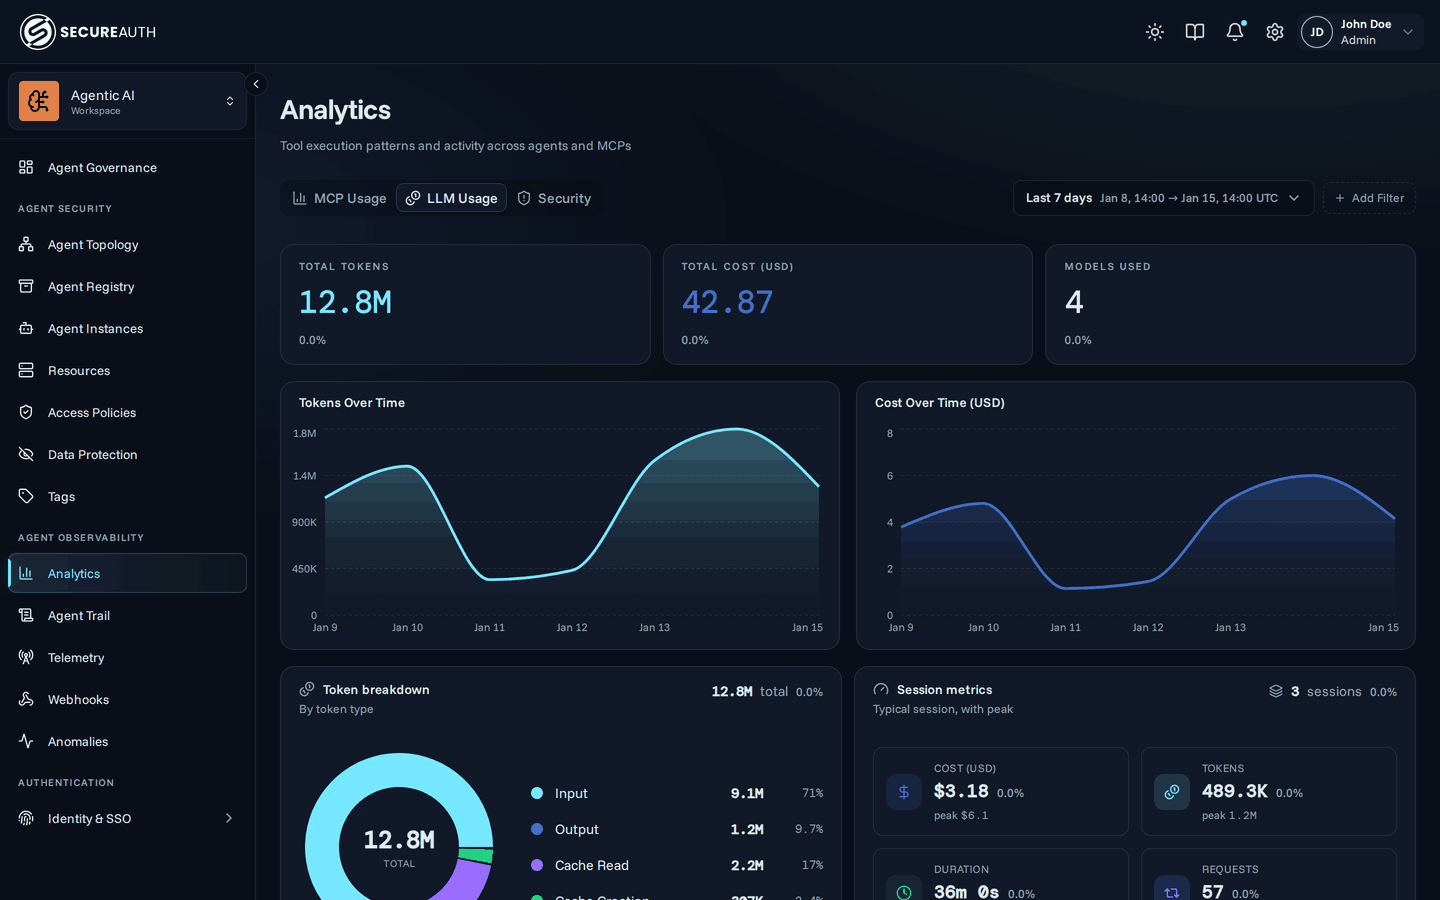
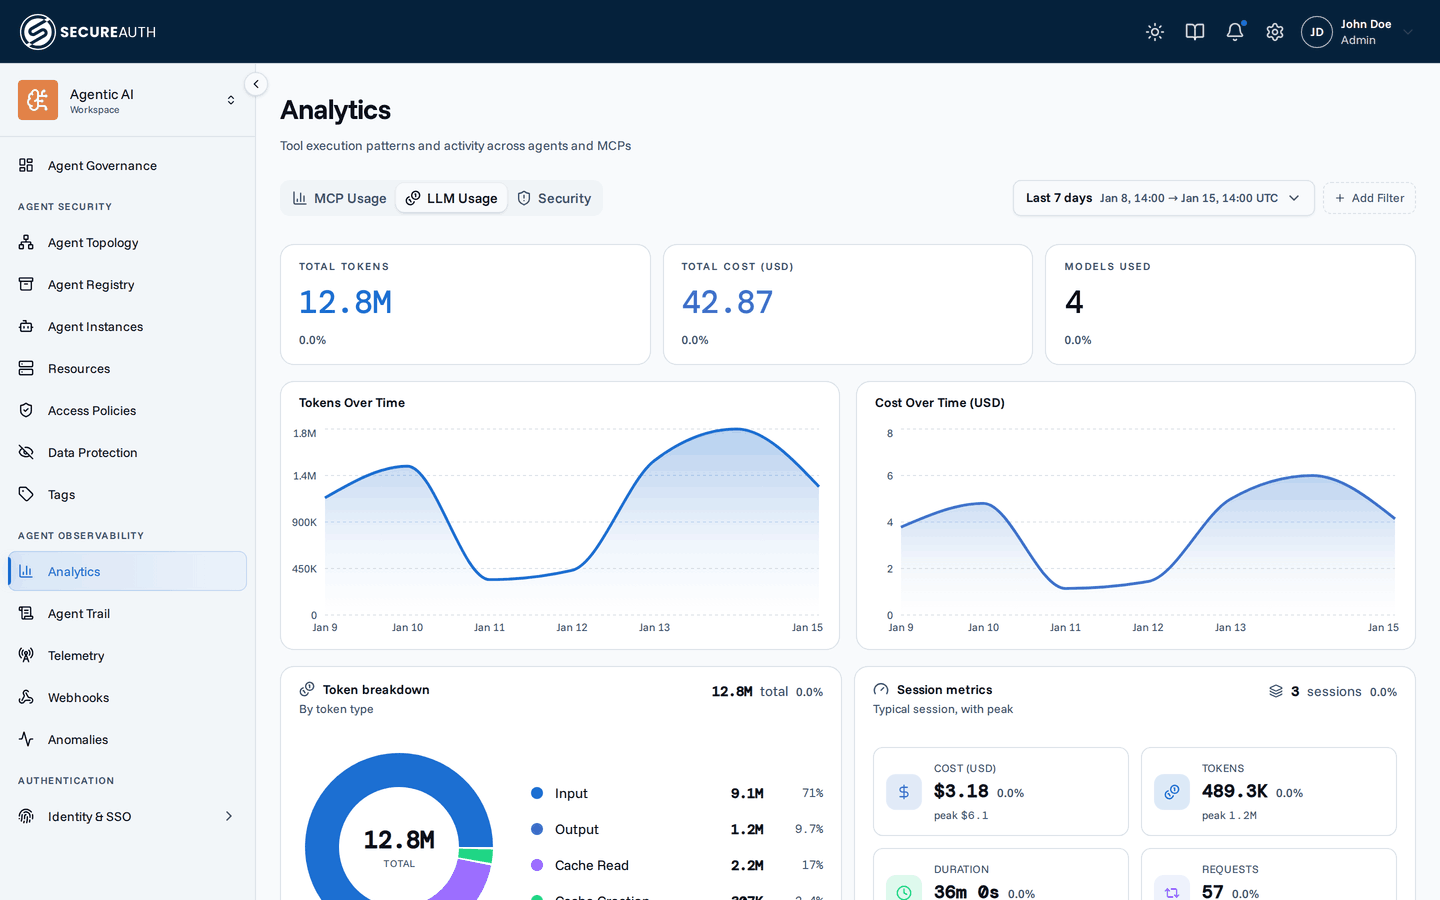
Token consumption across your coding agents, powered by OpenTelemetry data they send to the gateway. This tab is deliberately dollar-free; every cost measure lives on the dedicated Cost and adoption page:
- Total tokens and models used – headline figures for the selected period
- Tokens by type – usage split across input, output, and cache token types
- Tokens over time – a line chart of consumption trends, overlaying a hatched API-key series over the total so you can read the metered-usage share against the whole at a glance
- Top Users by Tokens and Top Models by Tokens – which users and models consume the most (paginated, 10 per page)
You see this tab only if your role grants view_llm_analytics for the whole organization.
Until your agents are configured to send telemetry, it shows an empty state linking to the Discovery Sources page;
see the OpenTelemetry guide for how to connect Claude Code and Cowork, Codex, GitHub Copilot, and Gemini CLI, including turning it on org-wide.
Claude Code and Cowork usage comes only from the telemetry logs exporter (its api_request event), so a Claude agent that exports only metrics shows no LLM usage.
Auth mode: subscription, API, or unknown
Every usage row is classified by auth mode (how the session authenticated):
subscription (a logged-in account seat), api (a metered API key), or unknown when the signal is missing.
Codex and Gemini CLI report this explicitly, and Copilot is classified by the model provider it names;
Claude infers it from whether account identity is present on the telemetry (present means subscription, absent means API key).
Use the Auth mode filter to narrow any chart or table to one bucket.
Auth mode is a provable authentication path, not a billing-truth signal: telemetry has no field for whether a given request landed within a subscription's included usage or spilled into overage, so treat it as a proxy for billing mode rather than the mode itself. The dollar measures built on this split (real spend, API-equivalent, savings) live on the Cost and adoption page.
The Sessions area doesn't carry this dimension: per-session rows aren't split by auth path in v1, so the Auth mode filter has no effect there.
Per-session usage
The Sessions table ranks individual agent sessions by token consumption or recency. Each session reported by an agent becomes one row in the table. The Agent column names the agent that ran each session, for example Claude Code.
Click any row to open the Session timeline drawer. Alongside the session's totals, model breakdown, and token mix, it charts tokens over time (bucketed, so you can see when the agent was working hard versus idle). A per-model rollup drives the Models card and average latency. Below the charts, a Requests table lists the session's individual requests (time, model, token split, duration, and prompt), 20 rows per page.
Note: Claude, Codex, and Gemini CLI sessions are built entirely from their event logs, so an agent exporting only metrics produces no session row at all. Copilot sessions are built from its trace spans, grouped by the conversation id it reports, or by the parent chat session id when a background call reports no conversation of its own.
Session metrics
Above the Sessions table, the Session metrics panel summarizes the distribution of sessions that match the current date range and filters. For each of the three dimensions (tokens, duration, and requests) it shows the median as the headline figure with the P95 peak beneath it, alongside the session count; each figure carries a delta against the previous period. Dollar figures live on the Cost and adoption page, so this panel is deliberately dollar-free. This lets you see at a glance what a "normal" session looks like and how far the tail extends.
The panel respects the same telemetry provider, model, agent, user, group, and date-range filters as the rest of the LLM Usage tab, so you can narrow it to a single model or user and immediately see how their sessions compare to the broader baseline.
The session drawer is dollar-free in v1: it reports tokens, duration, and model mix, but no per-session cost. Every dollar-denominated figure, including per-session, lives on the Cost and adoption page.
Where this session lands
The session drawer includes a Where this session lands panel that answers "was this session unusual?" without making you scan raw numbers. It opens with a plain-language verdict ("A typical session - close to your org's median on every metric" or "An ordinary session that spiked - top 3% on tokens"), then plots the session on one lane per dimension (Requests, Tokens, Duration).
Each lane is a percentile axis running from quietest to heaviest, with a shaded band for the common range (P10–P90), a darker band for the typical range (P25–P75), and a spine at the median.
A dot marks where this session sits, and a caption gives its rank: top 5%, bottom 8%, 57th pct.
Ranks are clamped to what the sample can support, so a small org can't be told "top 1%" out of eight sessions.
Sessions at or above P95 are highlighted in amber, but only once the baseline holds at least 20 sessions;
below that the position is shown without the outlier treatment.
The comparison is independent of the tab's filters:
the session is ranked against all of your organization's sessions in the panel's own window, which you toggle between 7d, 30d, and 90d.
The header reads "ranked against N sessions" so you always know the sample size.
With fewer than two sessions to compare against, the panel says so rather than comparing.
Filters
Every tab shares the date-range picker (see below) and User and Group filters. Selecting one or more groups narrows the charts to their current members; membership is evaluated as it stands today, the same way the User filter works. The LLM Usage tab adds Telemetry provider (the agent's own OpenTelemetry export that reported the usage), Model, Auth mode, and Agent (the agent that ran the session).
Filters combine. For the date-range picker, see Date-range picker.
Next steps
You can now read token use per user, model and session, and tell an unusual session from a normal one. Next, put a dollar figure on it.
- Cost and adoption – spend by team, model and person.
- OpenTelemetry – connect Claude Code, Codex, Copilot, and Gemini CLI to populate this tab.